A month-long agent fails in three places. It never trained on problems where actions play out over days. It can't coordinate with the agents beside it. And holding all that context in memory gets too expensive to run. Each track takes one of those on.
01 · Where agents learn
Simulation RL environments
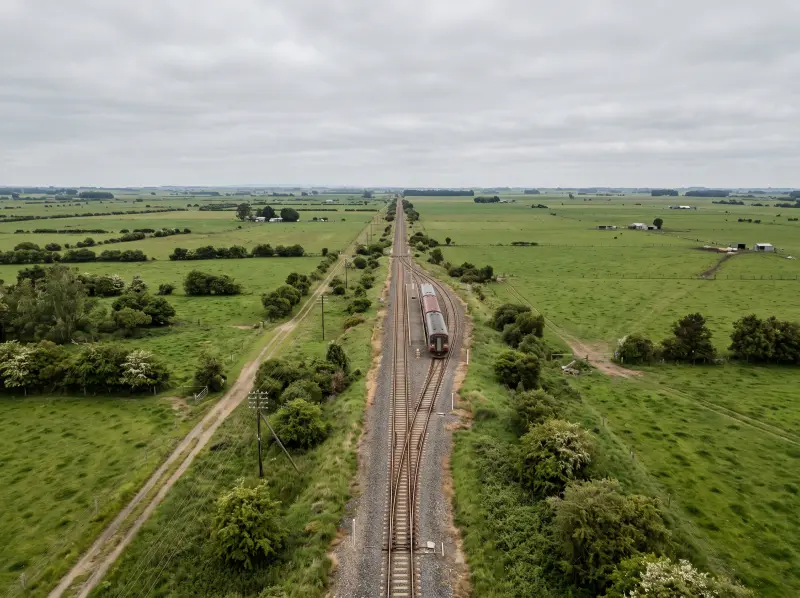
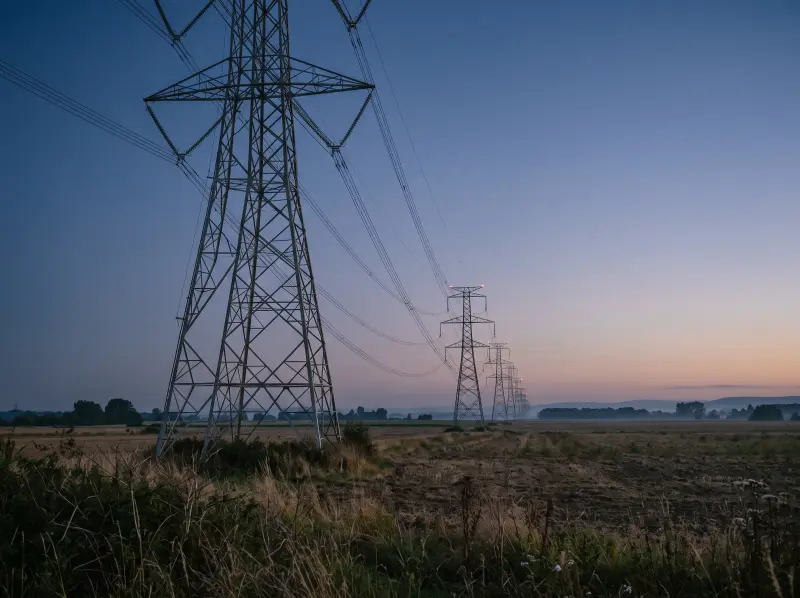
Digital twins of real operations, rebuilt from public records: rail networks recovering from real disruptions first, then power-grid redispatch. The agent replans as the day unfolds, and every plan is graded against a proven optimum.
02 · How agents run
Long-running agent swarms
Swarms of up to 10,000 agents that share state through a REPL, as in Recursive Language Models. Agents hand off work as variables, and every result can be checked by code.
03 · What it costs
The KV cache, up close
Every agent's memory lives in the KV cache. We study how KDA, CSA, FlashAttention, vLLM and RadixAttention shape it, and what it takes to keep thousands of agents running at once.